Automated public-data collection pipeline
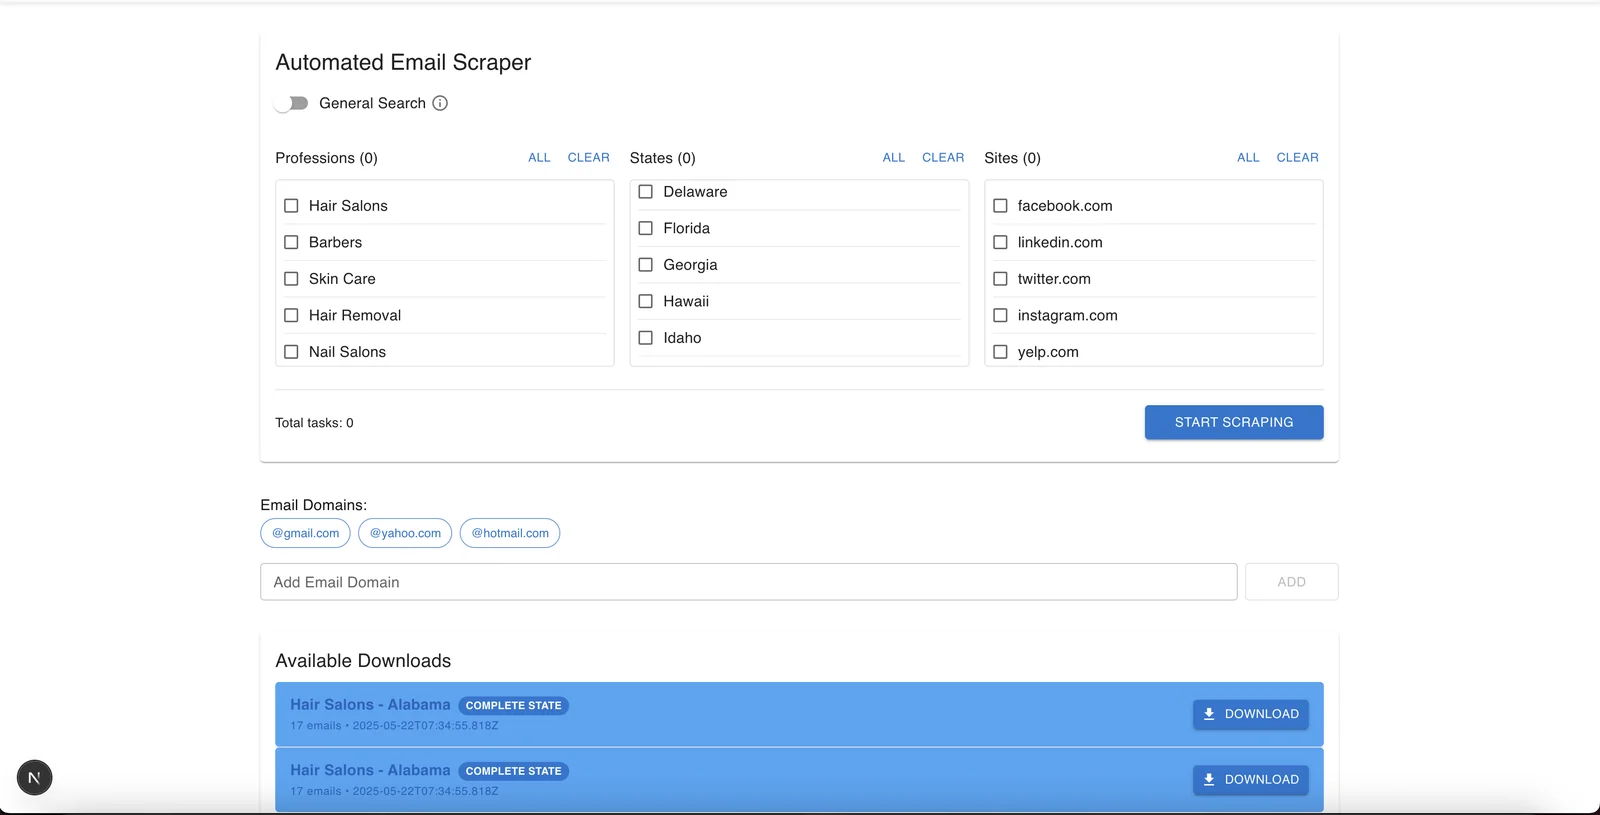
A public-data extraction project built with Next.js, TypeScript and Bright Data proxies to reduce manual aggregation work.
The project
This project involved collecting public information at scale. Manual aggregation made the workflow repetitive, so the development work focused on extracting data through a repeatable pipeline.
My contribution
I built the extraction pipeline using Next.js, TypeScript and Bright Data proxies. The work involved automating public-data collection and preparing information for the next step in the workflow.
Questions that shape a data pipeline
The data sources, permitted access, output format and update schedule affect the implementation. Source pages can change, requests can fail and records can be incomplete, so those situations should be considered when defining the process.
Planning your own workflow
A useful brief identifies where the data comes from, which fields you need, how often it should update and who will use it. A sample output makes it easier to agree what the pipeline should produce and how to check the result.
Discuss a similar project
Explore my data automation and API integration or send a project enquiry with your requirements and preferred timeline.
Need Automated Data Collection?
I can build scraping pipelines tailored to your data sources and scale.
Get in Touch →